The paid shelf enters the answer
A shopper asks for dinner ideas and receives a short list of ingredients. One product in that list is sponsored. The commercial opportunity is clear: the ad reaches someone while a basket is taking shape. The harder question is what the shopper thinks the assistant has done on their behalf.
Kroger Precision Marketing's August 3, 2026 announcement says product listing ads can appear in its AI Shopping Assistant when relevant to the request. They're labeled as sponsored. Existing Search & Browse PLA ad groups are included automatically, and advertisers can use its report builder to inspect assistant performance separately.
Keep these three meanings separate
Paid visibility
A product receives a sponsored placement.
Product relevance
The product fits some part of the request.
Suitability
The shopper's actual constraints are satisfied.
KPM senior vice president Nick Hamilton describes the launch as “another way to be discovered in the exact moments when shoppers are planning meals and building their baskets.” That is the supplier’s stated opportunity. It still leaves the advertiser to establish which placements help the customer and what they earn.
That mechanism is more specific than saying recommendations have become advertisements. A sponsored listing is a paid placement in the experience. It doesn't prove that the whole answer was bought, that a bid controls every product selected, or that the assistant has independently established the promoted item as the best choice. Those distinctions should survive the headline.
Google is exploring a related boundary. In its May 20 description of new Search ad formats, the company says it's testing sponsored formats with an AI-generated explainer alongside advertiser creative. Highlighted Answers can place eligible ads within recommendation lists. The announcement describes tests and upcoming features, so it shouldn't be read as universal access for every campaign.
The shift deserves attention because the request can contain much more than a keyword. A customer might explain who the meal is for, how much time they have, and what they can't use. A paid product placed beside the resulting advice borrows that context. My concern is how easily contextual relevance can be mistaken for a complete check of the product.
Compare the new surface with the existing campaign before calling it a new channel. Automatic inclusion can redistribute the same budget into additional inventory. Check whether the campaign's reporting separates that shift clearly enough to support an investment decision. A new placement name doesn't necessarily mean a separately controlled budget.
A retail media brief therefore needs to specify what the advertiser is purchasing. Is it eligibility for a sponsored slot, a product click, or an interaction with a brand-controlled assistant? Ask for the actual placement and its disclosure. A category called AI shopping is too broad to tell the team what promise it must be ready to support.
Product data becomes part of the pitch
A product feed gives a platform structured facts about an item: its identity, price, stock status, and other attributes. In an assistant-led experience, those facts can also help shape the explanation a customer sees. That's a reason to make the data precise before spending more to distribute it.
Google Merchant Center's product specification requires availability to match the landing page, checkout, and structured data. It also defines identifiers and variant attributes. These are Google's requirements, not a universal specification for every assistant, but they illustrate the practical problem. An item can't be described reliably when its own records disagree.
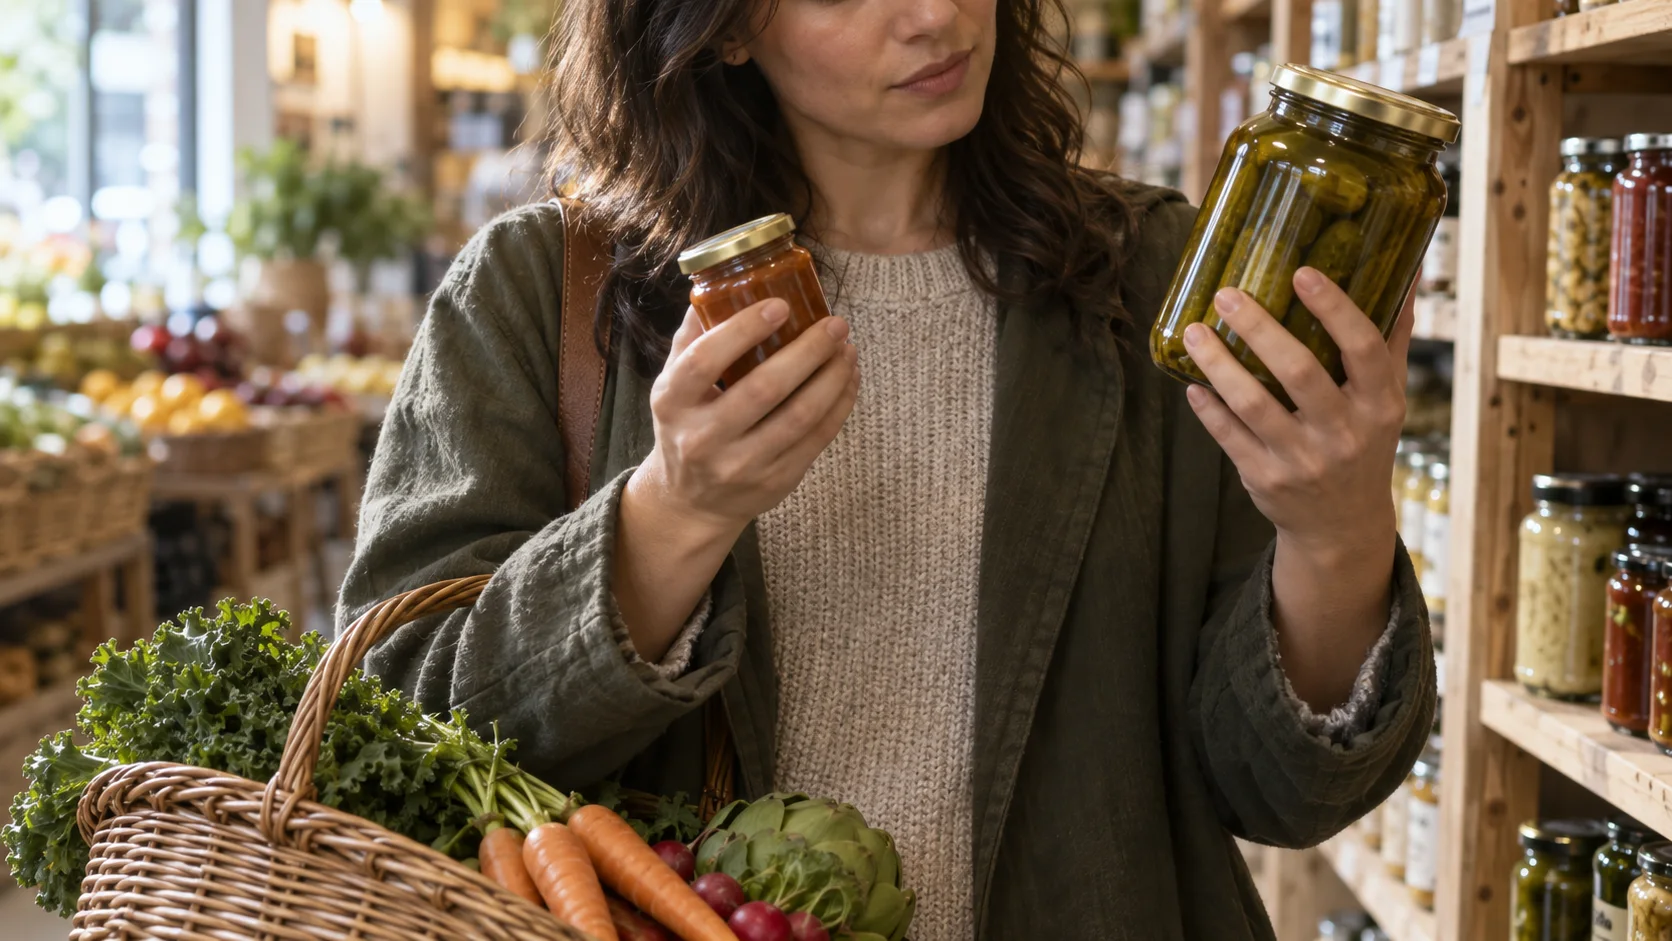
Consider an illustrative jar of sauce. The feed names the brand and flavor but omits the pack size. The page opens on a single jar, while the offer price refers to a multipack. The assistant may retrieve individually accurate fragments and combine them into a misleading comparison. The first repair is to make the offer consistent across every surface.
For priority products, translate internal shorthand into customer language. A merchandising team may understand a variant code that tells a shopper nothing. State what changes between the variants, what comes in the package, and which conditions limit an offer. Treat these as facts to maintain, with a named owner, rather than extra keywords to stuff into a title.
Keep unsupported claims out of the record even when they sound persuasive. If a product description implies compatibility or a dietary property, the evidence needs to support that exact version of the product. A generated explanation can magnify a casual phrase into a stronger promise. Removing ambiguity at the source is easier than correcting every sentence an assistant might produce later.
Document who can change a fact after approval. Supplier updates, ecommerce edits, and promotional imports can all reach the same listing. If each system can overwrite the others, an accurate launch audit has a short shelf life. Assign a clear source for each field.
Refresh frequency should follow how quickly the fact changes. A material specification may remain stable for months. Local inventory or a promotion can change during the day. Build an escalation path for a mismatch, including who can stop paid distribution while the record is corrected. Buying more exposure for stale information makes a preventable customer problem more expensive.
Test the request a shopper would make
A feed audit alone won't show whether the shopping experience preserves a person's constraints. You need to inspect the path from a request to the product offered. Start with a small, repeatable set of realistic needs, written in the language customers use with your service team.
For an illustrative grocery category, that could include a quick family meal, a fixed total basket budget, or a request for a small pack. Vary one constraint at a time. Record which products appear, whether sponsorship is visible, and whether the explanation stays faithful to the selected item. Don't turn a single favorable screenshot into a general visibility claim.
The request narrows the shelf

Include requests your product should lose. A large multipack isn't the right answer when someone needs one small portion. A premium item may not fit a strict budget. If the assistant keeps promoting the product through those conflicts, you have found a quality issue to raise with the platform, not a reason to celebrate unusually broad relevance.
Keep sensitive attributes on a tighter standard. A diet-related request or a product compatibility question may have consequences beyond disappointment. Validate the actual label or manufacturer information and route ambiguous cases to a responsible reviewer. The point of the exercise is to identify whether an explanation exceeds the evidence available, not to invent a marketing-friendly interpretation.
Repeat the observations with their context attached. Availability, location, account history, and wording may affect what appears. Describe the sample as a sample. Your team can measure consistency across its own test set without pretending to know the assistant's entire ranking system or the experience of every shopper.
Use support questions to keep the test set grounded. Questions about quantity, delivery, or returns reveal where customers already struggle. They often make better evaluation prompts than clever adversarial riddles because a correction improves the ordinary shopping experience as well as the assistant's answer.
Connect findings back to the product owner. A mismatch with the catalog needs a data repair. A correct record interpreted too broadly needs a platform report and possibly a pause in the placement. An item that simply doesn't suit the request may need to be excluded from that intent. Different failures call for different fixes, even if they all lower conversion.
Disclosure must survive the conversation
A sponsored label has to be understood at the moment commercial influence matters. If the user reads an explanation as neutral advice and discovers the sponsorship only after clicking, the disclosure has missed much of its job. The design of the interaction matters as much as the existence of a label.
The FTC's native advertising guidance says necessary disclosures must be clear and prominent, close to the advertising, and understandable on the devices where people encounter it. That's established US advertising guidance, not a new AI-specific rule. Applying it to a particular format requires attention to the overall impression the format creates.
The paid label travels with the product

For a conversational placement, I'd inspect the first answer and the follow-up. Does the label remain associated with the promoted item when the shopper asks for a comparison? Can a screenshot or expanded panel make a sponsored suggestion appear independent? Can a reader identify which statement came from the advertiser and which was generated by the platform?
The answer doesn't require filling the page with legal text. It requires a recognizable ad label, a clear relationship between label and product, and no contradictory design cues. A faint label that technically exists can be harder to notice than a bold recommendation calling the product a perfect match.
Advertisers don't control every part of a retailer's interface. They can still request examples, document concerns, and make the placement's terms part of the buying decision. If a platform won't explain how paid content is distinguished from its own advice, that uncertainty belongs in the campaign assessment before spend expands.
Invite someone unfamiliar with the campaign to inspect the placement without coaching. Ask what they believe was paid for and who they think is making the recommendation. Treat confusion as a design observation to investigate, even when the campaign team can easily locate the label.
There's a defensible case for helpful sponsored products. An available product with clear evidence and visible sponsorship can answer a real need. The concern is the extra authority implied by an assistant's tone. A brand benefits when the user can understand the commercial relationship without having to investigate it.
Measure the sale without inventing influence
An ad inside a shopping conversation can receive a click, contribute to a basket, or be ignored. It might also affect a later purchase that the report doesn't connect. The possibility of influence beyond the click is real as a hypothesis. It isn't a license to assign extra value to every missing signal.
IAB Europe's 2026 commerce measurement standards distinguish incrementality and define reporting expectations, including timeframes for new-to-brand and new-to-category measures. New-to-brand describes purchase history within a defined window. It doesn't, by itself, establish that the ad caused the customer to buy.
Build a report that answers separate questions. Delivery asks whether the paid placement appeared and received engagement. Commerce asks which products were bought and what happened after the order. An experimental comparison asks whether additional value was created. Combining those questions into one return figure can conceal both a useful campaign and an ineffective one.
Keep the product and the basket distinct. A promoted ingredient might receive credit for a larger grocery order, depending on the retailer's attribution rules. Find out what the reported sales include, how long the attribution window lasts, and whether returns or cancellations are removed. Without those definitions, two impressive reports may be measuring different things.
For an available randomized test, compare eligible shoppers who can receive the placement with a suitable holdout. If that isn't possible, ask what alternative design is available and what uncertainty it leaves. IAB's incremental commerce measurement guidance is a useful starting point for a discussion about methods rather than a guarantee that every retailer offers the same test.
Look for substitution within your own range. An ad can move a customer from one of your products to another without increasing the basket's value. That may be useful for a launch or stock-management objective, but it needs its own commercial justification. More attributed sales of the promoted item can hide that transfer.
Small trials won't always resolve a sales effect. They can still expose incorrect product information, poor disclosure, or a high cancellation rate. Record those findings separately from the effect estimate. A campaign doesn't become successful because the sample is too small to prove it failed, and it doesn't become useless because a reliable sales result needs more time.
Write a brief the shelf can honor
Start the buying brief with the customer situation and the exact products that can satisfy it. Include who owns the product facts, which claims are supported, and when inventory should remove an item from paid consideration. An audience description alone doesn't tell the team whether the offer belongs in an assistant's answer.
Choose the launch set with the merchandising team. A smaller group of well-understood products is easier to investigate than an entire catalog with inconsistent variants. Give each item a clear destination and a current offer. That creates a manageable test of AI-mediated product discovery while the team learns what the surface can actually explain.
Three owners behind one recommendation
Merchandising
The product facts and offer are correct.
Media
The placement and measurement are understood.
Operations
The customer can receive what was promised.
Specify the learning question before the campaign runs. You might be testing whether a new placement introduces the product to suitable customers, whether explanations improve product understanding, or whether the buying path creates profitable additional orders. Pick the evidence that can answer that question. Otherwise the report will default to whatever metric is easiest to obtain.
Include a repair owner and response deadline. If the assistant quotes an obsolete offer, media needs a way to stop further exposure while merchandising corrects it. If the pickup promise fails, fulfillment needs the original product and location context. A useful incident record follows the customer promise across teams rather than stopping at the ad click.
Keep a record of the interactions you inspect, with unnecessary personal information removed. Save the prompt, product variant, offer, disclosure, destination, and date. This gives the platform something reproducible to investigate and helps the next reviewer distinguish a new problem from an old one. Don't collect a shopper's private conversation just to make the report feel complete.
The brief should also define what the trial won't answer. A limited grocery placement can't establish that every product category will perform similarly. Keeping that scope visible protects the next budget decision from an attractive case study whose conditions no longer match.
Finally, decide what earns a larger budget. It should include reliable product fit, an understandable commercial relationship, and evidence proportionate to the claim you're making about performance. If only the delivery metrics are available, call it a delivery result. That discipline makes a promising new placement easier to evaluate without either dismissing it or inventing its value.