The Silent Failures Killing Agent ROI
Agentic AI drift rarely breaks the system. It changes the route the system takes, one decision at a time, until the same green dashboard is paying for different behavior.
The old failure model was binary: the agent worked or it crashed. Production agents fail in more slippery ways. They remember the wrong thing, trust the wrong tool, escalate the wrong message, skip a tired approval gate, or drift into a new operating pattern while every high-level metric still looks calm.
7
new Microsoft v2.0 failure categories
13
symptom classes in an open-source fault study
1
workflow owner who can roll it back
Failure moved inside the run
An agent becomes dangerous when it keeps acting after its reasoning path has changed.
When Microsoft's AI Red Team published its first agentic failure taxonomy in April 2025, the useful move was vocabulary. It separated safety failures from security failures, then separated failures that are novel to agents from older model risks that become sharper once a system can plan, call tools, persist memory, and affect real workflows.
The June 2026 update tightened the point. Microsoft said the v2.0 taxonomy was grounded in 12 months of red-team engagements against deployed agentic systems. The update added seven categories, including agentic supply chain compromise, goal hijacking, inter-agent trust escalation, computer-use visual attacks, session context contamination, MCP or plugin abuse, and capability disclosure.
That list matters because it moves the failure out of the model box. The weak spot may be a tool description, an approval prompt, a poisoned memory, a trusted sub-agent, a misleading UI, or a context trail that nudges the next step. A model accuracy dashboard will not catch that class of drift.
A taxonomy also keeps the response grounded. Without one, every bad run becomes a prompt problem, a vendor problem, or a model problem. With one, the operator can ask where the behavior changed: cognition, memory, tool selection, context grounding, permission design, or the human review step.
The six failure buckets
Microsoft's taxonomy is broad because it is built for builders, red teamers, and defenders. Marketing teams need a simpler lens for operating decisions. When an agent moves budget, chooses audiences, writes claims, routes customers, or changes offers, sort failures into six buckets before arguing about the model.
The buckets are intentionally practical. They tell a CMO whether to inspect uptime, refresh market data, replay behavior, clean context, quarantine a tool, or redesign approvals. Silent failure gets expensive when all six problems are treated as the same vague "AI quality" issue.
Crash
The system fails loud
API errors, timeout storms, schema breaks, and rate limits still matter. They are the easy class because logs and uptime monitors were built for them.
Decay
The world outruns the model
Customer behavior, inventory, policy, search results, and competitor moves change. The model keeps answering from a weaker map of reality.
Drift
The behavior shifts
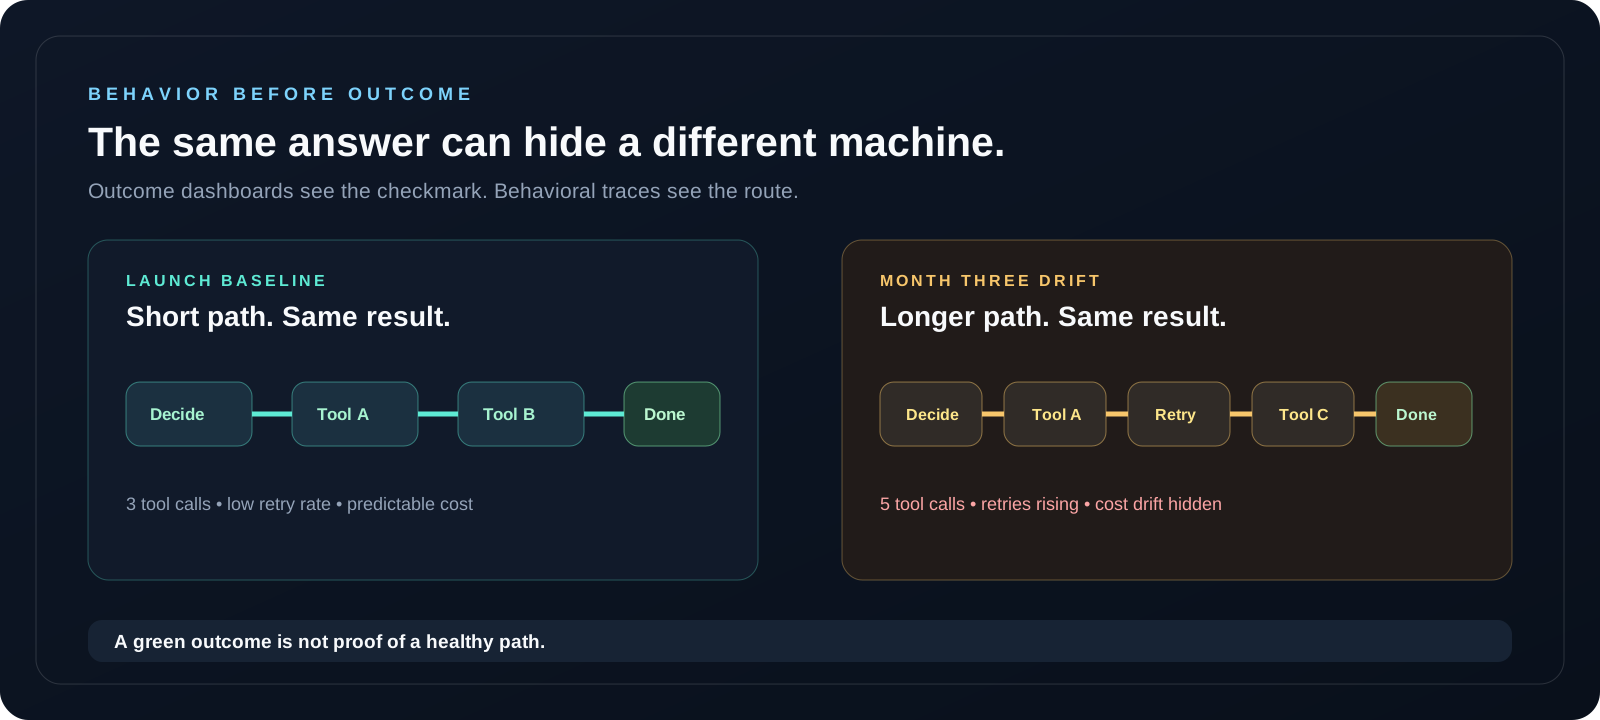
The agent still completes the job, but its routes, retries, tool choices, or escalation habits move away from the launch baseline.
Contamination
The session bends the next step
Earlier retrieved content, memory, or user input changes what later instructions mean. No single action looks broken enough to trigger review.
Compromise
The tool becomes instruction
A plugin, MCP server, prompt template, or tool description can redirect behavior through natural language without changing the code path.
Approval bypass
The human stops being a control
Consent fatigue, summary laundering, and repeated low-stakes approvals train reviewers to accept actions they no longer inspect.
Why dashboards miss the change
A dashboard sees the result. A taxonomy has to see the chain that produced it.
A 2026 preprint on agentic AI faults analyzed 13,602 closed issues and pull requests across 40 open-source agentic repositories, then manually reviewed 385 representative faults and validated the taxonomy with 145 practitioners. The relevant finding for operators is plain: agent failures often propagate across cognitive control, tool actuation, memory, runtime grounding, and observability.
Practitioners in that study separated syntax failures from semantic failures. A syntax failure is easy: the JSON breaks or the tool call fails. A semantic failure can pass the schema while being wrong, inconsistent, or misaligned with the ground truth. Those are the failures that creep through a marketing workflow.
That distinction explains why outcome dashboards lag. They see the final campaign state, support reply, audience export, or offer change. They rarely preserve the intermediate judgment: which policy the agent applied, which retrieval result it trusted, which tool response it discarded, and which approval summary shaped the human click.
Standard dashboards compress thousands of choices into a few outcome metrics. Conversion rate, cost per acquisition, and return on ad spend can hold steady while the agent has shifted toward safer copy, weaker audiences, more expensive tools, or fewer edge-case escalations. The metric moves after the behavior moves. By then, the agent has trained the process around its new habits.
Marketing makes drift expensive
Marketing agents operate inside delayed feedback. An email sequence decision can take days to show fatigue. A paid media audience change can look fine until frequency rises. A support answer can sound plausible until customers churn for reasons the dashboard files under "other." The agent keeps moving while the evidence limps in late.
That delay changes the economics. A human analyst usually waits for enough evidence to change a campaign. An agent can make hundreds of small routing, copy, and bid decisions before the first clean signal arrives. The failure pattern looks operational, but the invoice shows up as wasted spend, weaker learning data, and slower recovery.
The danger is not one bad recommendation. The danger is compounding. A budget agent favors a slightly cheaper segment, then writes more copy for that segment, then feeds the new performance data back into the next budget cycle. A personalization agent suppresses uncertain edge cases, then learns from cleaner but narrower outcomes. The workflow starts optimizing around what the agent made easiest to measure.
The tau-bench paper is useful because it evaluates agents across repeated trials, not a single demo. It introduced pass-k reliability to ask whether an agent behaves consistently over multiple runs. For marketing leaders, that should be the default question: would this agent make the same kind of decision tomorrow with the same policy, or did we happen to catch one good run?
Gartner's 2025 agentic AI forecast adds the business consequence. It predicted that more than 40 percent of agentic AI projects will be canceled by the end of 2027, citing escalating cost, unclear business value, and weak risk controls. All three are symptoms of agents operating faster than the evidence layer around them.
The operating response
A louder dashboard will not fix silent failure. The system needs a record of behavior and a way to compare it.
OpenTelemetry's 2026 GenAI observability guide points in the right direction: record the model call, token counts, prompts, completions, tool calls, and tool results where capture is appropriate. That is the base layer. For agents, add task identity, policy version, retrieved context, tool result provenance, reviewer action, and final business decision.
The replay set should include normal tasks, edge cases, known abuse attempts, stale data prompts, tool outages, and approval requests that used to require human judgment. Drift becomes visible when the same scenario starts producing a different tool path, a different confidence pattern, a higher retry count, or a different handoff decision.
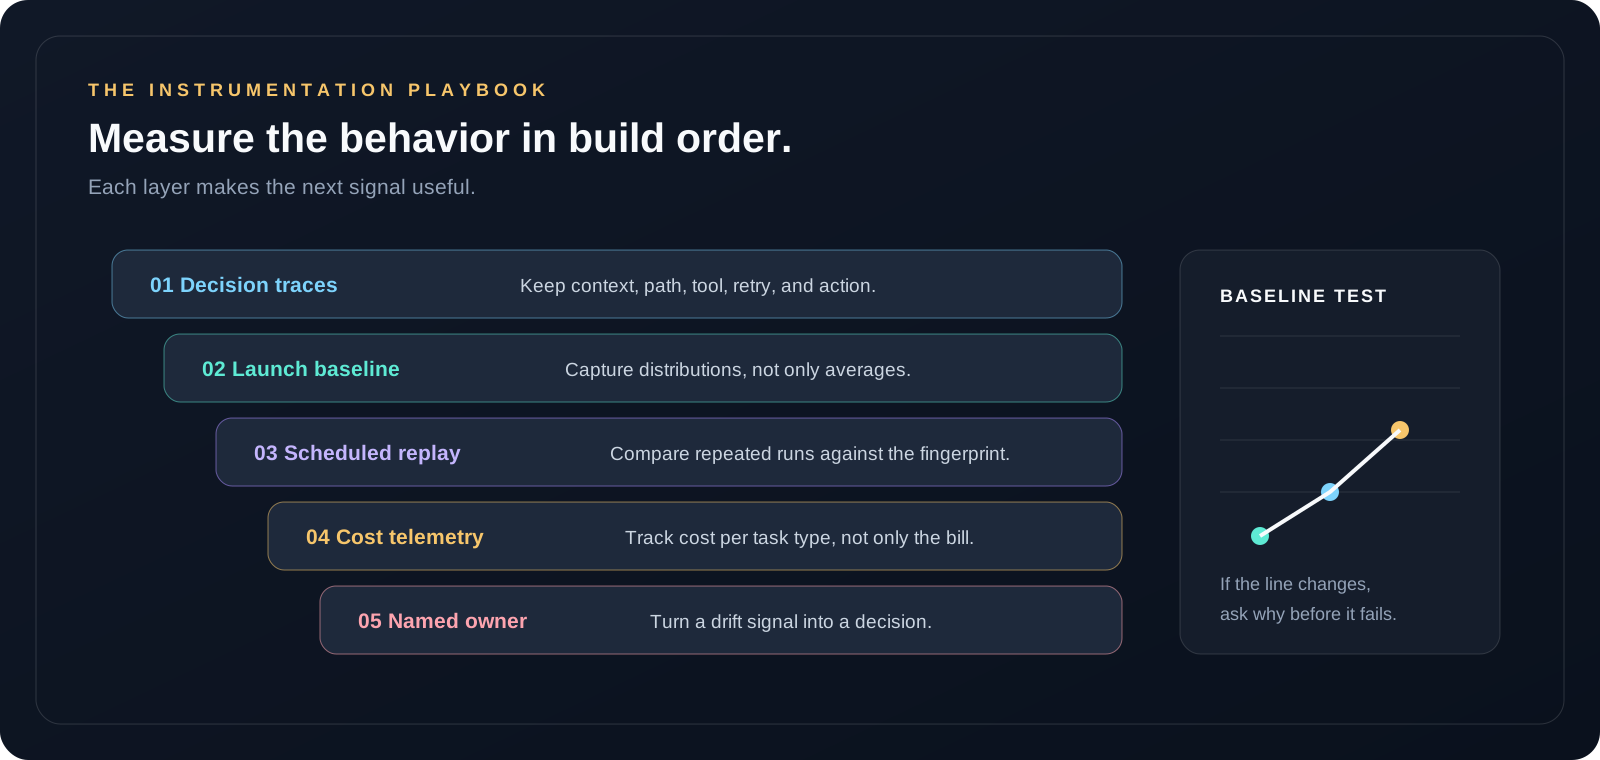
The response is plain, which is why it works. Capture the launch fingerprint. Log the decisions. Replay the same work. Separate drift from decay. Escalate by blast radius. Name the person who can stop the workflow when the signal turns red.
The companion measurement piece, Agentic AI Drift: The Measurement Blind Spot, turns the same operating idea into metrics. This page names the failure modes; the measurement work makes them inspectable.
Capture the launch fingerprint
Before the agent owns budget, offers, claims, or customer action, run a fixed scenario set and store the paths, tool calls, retries, cost, and final actions.
Log decisions, not vibes
Keep the input, retrieved context, selected tool, policy applied, rejected options, timestamp, and reviewer action. A success flag is too thin.
Replay the same jobs
Weekly or after every model, prompt, tool, or policy change, run the same tasks again. Compare distributions instead of admiring one lucky pass.
Separate drift from decay
If the same inputs now produce different behavior, inspect the agent. If new market conditions are the cause, refresh the data or model.
Escalate by blast radius
Budget moves, regulated claims, vulnerable-audience decisions, and customer-impacting actions deserve tougher approval than reversible drafts.
Name the owner
The owner is the person accountable for the workflow result. Prompt authors and vendors can help, but the business decision needs one name beside it.
The approval queue is part of the system
Microsoft's v2.0 update calls out human-in-the-loop bypass and consent fatigue because an approval step can become ritual instead of control. The agent decomposes a risky action into small requests. The reviewer sees familiar summaries. The next approval gets easier. Eventually the human is providing ceremony, not judgment.
Approval design should change with blast radius. Let low-risk drafts flow. Slow down money movement, regulated claims, sensitive audience decisions, irreversible customer actions, and tool changes that expand what the agent can touch. The permission model is part of the product, not paperwork after launch.
Where the owner sits
Prompt authors can improve the agent, and vendors can improve the platform. Workflow accountability sits with the person responsible for the result: paid media efficiency, lifecycle revenue, customer response quality, claims accuracy, lead routing, or support deflection. That person decides which changes require review, which metrics are too delayed to trust, and which baseline gets restored during a drift event.
Ownership also sets the rollback threshold. If a model upgrade, prompt change, new tool, or memory update shifts behavior beyond tolerance, the owner needs authority to pause the agent before the next reporting cycle. Otherwise drift becomes a debate about whether the dashboard has moved enough to justify action.
Regulation is already teaching the same habit in higher-risk systems. EU AI Act Article 72 requires providers of high-risk AI systems to document a post-market monitoring system that collects and analyzes performance data across the system's lifetime. Most marketing agents will not fall into that high-risk bucket. The operating lesson still travels well: a system that acts after launch needs evidence after launch.
The practical question for a CMO is blunt. If the agent changed its audience logic, offer policy, retrieval source, or approval behavior three weeks ago, who would know, what record would prove it, and who could roll it back today?
FAQs
What is agentic AI drift?+
Agentic AI drift is a change in how an agent decides while it keeps completing work. The output may still look acceptable, but the path, tool use, retry pattern, cost, escalation logic, or approval behavior has moved away from the launch baseline.
How is drift different from model decay?+
Model decay means reality changed and the model is less accurate against the world. Agent drift means the operating behavior changed. The same task may now trigger a different route, tool, policy interpretation, or handoff even when the outside world is stable.
Which agent failures are hardest to detect?+
The hardest failures are semantically valid and operationally wrong. The schema passes, the tool call succeeds, and the customer may even receive a plausible answer. The failure sits in the decision path, not the syntax.
What should marketing teams measure first?+
Start with decision traces. Track which audience, offer, budget, channel, claim, or response path the agent selected, what context it used, what it rejected, and whether a human approval changed the action.
Does every marketing agent need a heavy governance program?+
No. A draft-writing assistant and a budget-moving agent should not carry the same controls. Scale the review to the blast radius: money movement, compliance exposure, customer harm, reversibility, and whether the action can compound.
A useful agent can change its mind.
A governed one leaves evidence.